<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://olliestanley.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://olliestanley.github.io/" rel="alternate" type="text/html" /><updated>2025-10-06T11:48:59+00:00</updated><id>https://olliestanley.github.io/feed.xml</id><title type="html">Oliver Stanley</title><subtitle>Thoughts on data, AI, economics, football</subtitle><author><name>Oliver Stanley</name></author><entry><title type="html">Reasoning Gym Paper</title><link href="https://olliestanley.github.io/2025/06/02/rg-paper.html" rel="alternate" type="text/html" title="Reasoning Gym Paper" /><published>2025-06-02T00:00:00+00:00</published><updated>2025-06-02T00:00:00+00:00</updated><id>https://olliestanley.github.io/2025/06/02/rg-paper</id><content type="html" xml:base="https://olliestanley.github.io/2025/06/02/rg-paper.html"><![CDATA[<p>Reasoning Gym aims to facilitating the training and evaluation of reasoning models by providing procedural dataset generators with the ability to generate virtually infinite diverse samples with finegrained difficulty configurations.</p>

<p>Today we released <a href="https://arxiv.org/abs/2505.24760">our paper on arXiv</a>. I also wrote a <a href="https://x.com/_OliverStanley/status/1929487448783933897">thread</a> with some of the key details.</p>

<hr />

<h3 id="interesting-tidbits">Interesting Tidbits</h3>

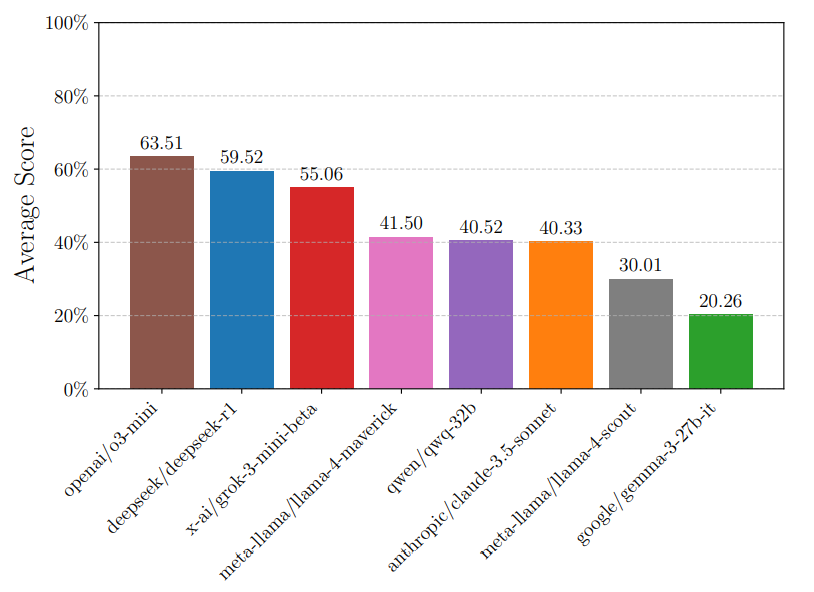
<p>We find that Reasoning Gym is a highly effective evaluation of frontier models’ problem solving capabilities. Here are results of several models on RG hard configs:</p>

<p><img src="/img/rghardeval.png" alt="RG Hard Eval" /></p>

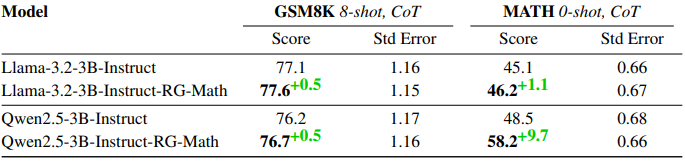
<p>Additionally, we run some small RL experiments and find that RLVR on RG mathematics data can improve models on common LLM benchmarks at the 3B scale.</p>

<p><img src="/img/rgtrain.png" alt="RG Train" /></p>

<p>RG has already been adopted for training and evaluation by NVIDIA researchers in their <a href="https://arxiv.org/abs/2505.24864">ProRL paper</a>.</p>

<p>It’s also possible to use RG data in William Brown’s <a href="https://github.com/willccbb/verifiers">popular <em>verifiers</em> RL library</a>, since he built a direct integration. Thanks to Will!</p>

<hr />

<h3 id="the-future">The Future</h3>

<p>We want to build an even bigger library of reasoning environments. If you have ideas, please feel free to let us know, or even contribute datasets generators directly via pull requests to <a href="https://github.com/open-thought/reasoning-gym/">our repository</a>.</p>

<p>Running more evaluations is also of interest. If anyone has OpenRouter or other API provider credits, we’d love to find out how more frontier models fare on RG tasks.</p>]]></content><author><name>Oliver Stanley</name></author><category term="AI" /><summary type="html"><![CDATA[Evaluation and RL training experiments with Reasoning Gym]]></summary></entry><entry><title type="html">Intro to Reasoning Gym</title><link href="https://olliestanley.github.io/2025/02/20/reasoning-gym-intro.html" rel="alternate" type="text/html" title="Intro to Reasoning Gym" /><published>2025-02-20T00:00:00+00:00</published><updated>2025-02-20T00:00:00+00:00</updated><id>https://olliestanley.github.io/2025/02/20/reasoning-gym-intro</id><content type="html" xml:base="https://olliestanley.github.io/2025/02/20/reasoning-gym-intro.html"><![CDATA[<p>Reasoning Gym is a new open-source project aimed at facilitating the training of reasoning models using finetuning techniques including reinforcement learning.</p>

<hr />

<h3 id="background">Background</h3>

<p>The open-source release of DeepSeek-R1 stirred up a lot of interest, in both international markets and the open-source AI community. Two of the key innovations justifying the excitement are:</p>

<ul>
  <li>GRPO, originally published in 2024 with DeepSeekMath, is more cost-effective than the dominant PPO for reinforcement learning on LLMs. GRPO removes the value function, reducing resource usage since the value function was typically a neural model of similar size to the policy model.</li>
  <li>Algorithmically verifiable problems as training data, allowing rules-based rewards in the RL process rather than a (difficult to train and often unreliable) neural reward model.</li>
</ul>

<hr />

<h3 id="goal">Goal</h3>

<p>Reasoning Gym seeks to take advantage of both of the mentioned DeepSeek innovations by building a procedural dataset generator for algorithmically verifiable problems. This will allow anyone to train reasoning models using an RL technique like GRPO, without going through the process of curating huge volumes of data.</p>

<p>Many datasets have configurable complexity or difficulty levels, allowing virtually infinite datasets of varying challenge levels.</p>

<p>To achieve this, contributors can write their own dataset classes in a range of categories such as games, logic puzzles, algorithms, coding, geometry, and others. My own first contribution to the project was a <a href="https://www.futoshiki.com/">Futoshiki</a> generator.</p>

<hr />

<h3 id="further-work">Further Work</h3>

<p>Going forwards a key aim is to build a “curriculum”, where data is generated with progressing levels of complexity, depending on the learning progress being made by the model being trained.</p>

<p>The repository for the project also contains <a href="https://github.com/open-thought/reasoning-gym/tree/main/examples">examples</a> for training LLMs using RL with various frameworks, including OpenRLHF, trl, and veRL.</p>

<p>Finally, building supplementary reasoning datasets, which are not procedurally generated, will be explored in order to augment the procedural generators.</p>

<hr />

<h3 id="contributing">Contributing</h3>

<p>Anyone can contribute to Reasoning Gym by commenting on the issues in the GitHub repository and raising pull requests. The <a href="https://github.com/open-thought/reasoning-gym/blob/main/README.md">project readme</a> also details how to join the community on Discord.</p>]]></content><author><name>Oliver Stanley</name></author><category term="AI" /><summary type="html"><![CDATA[Building procedural data generators to train reasoning models]]></summary></entry><entry><title type="html">First Open Assistant Models and Dataset Release</title><link href="https://olliestanley.github.io/2023/04/15/open-assistant-release.html" rel="alternate" type="text/html" title="First Open Assistant Models and Dataset Release" /><published>2023-04-15T00:00:00+00:00</published><updated>2023-04-15T00:00:00+00:00</updated><id>https://olliestanley.github.io/2023/04/15/open-assistant-release</id><content type="html" xml:base="https://olliestanley.github.io/2023/04/15/open-assistant-release.html"><![CDATA[<p>For the last four months I have been working on <a href="https://open-assistant.io/">OpenAssistant</a>, a volunteer project in collaboration with <a href="https://laion.ai/">LAION-AI</a> to create a fully open-source language model tuned to follow instructions as an alternative to proprietary services like ChatGPT. Today (15th April 2023) we release a high-quality instruction tuning dataset and the first versions of OpenAssistant models.</p>

<hr />

<h3 id="dataset">Dataset</h3>

<p>We release the first version of the <a href="https://huggingface.co/OpenAssistant/oasst1">OpenAssistant Conversations Dataset</a>, a fully volunteer-contributed dataset consisting of over 50,000 high-quality instruction and response pairs across multiple languages. The dataset is released under a permissive Creative Commons license, meaning it can be used for a wide range of purposes, including commercial. The instruction and response pairs have been used successfully to tune a pretrained large language model (LLM) to follow instructions using supervised finetuning (SFT), demonstrating their value.</p>

<p>In addition to the instruction and response pairs, we release accompanying label data from community moderation, with each message being rated by several users for categories such as whether it is spam, its quality, its helpfulness, and others. Finally, each prompt has multiple response options, and we release the accompanying human ranking data for relative ranking of the responses for each prompt. This data can be used to train reward models for reinforcement learning from human feedback (RLHF).</p>

<p>A more in-depth breakdown and analysis of the dataset will be available in the upcoming Open Assistant Dataset version 1 research paper.</p>

<hr />

<h3 id="models">Models</h3>

<p>We release a range of models tuned from two different base models, Pythia 12B, and LLaMa 30B.</p>

<p>Our <a href="https://huggingface.co/OpenAssistant/oasst-sft-4-pythia-12b-epoch-3.5">Pythia-based 12B parameter model</a> is released under the Apache 2.0 license, making it available for a wide range of uses including commercial. This is the most capable fully open-source instruction-tuned model available, having been trained on more data than others such as Databricks’ Dolly. While larger public instruction-tuned models exist, such as Vicuna, they are derived from LLaMa and therefore not fully open-source.</p>

<p>Our LLaMa-based 30B model will be released in the form of weight deltas, meaning you must have a copy of the original LLaMa weights in order to use it. The restrictions placed on the use of LLaMa models by Meta must also be followed, meaning the model is available only for research use.</p>

<p>We additionally release the reward model used for RLHF training under a permissive Apache 2.0 license.</p>

<hr />

<h3 id="chat-interface-and-safety">Chat Interface and Safety</h3>

<p>You can chat with an OpenAssistant LLaMa-based 30B model using the free chat interface <a href="https://open-assistant.io/chat">here</a>. This will also help us build better datasets and models as responses and feedback are recorded, so please use the thumbs up and down ratings liberally!</p>

<p>In conjunction with OpenAssistant, safety techniques for LLMs were developed under the <a href="https://github.com/LAION-AI/blade2blade">blade2blade</a> project. Our chat interface will soon use blade2blade to mitigate harms.</p>

<hr />

<h3 id="future-work">Future Work</h3>

<p>We will in future release improved models and models tuned with RLHF. We are additionally considering several streams of future work, including:</p>

<ul>
  <li>Tuning other open-source models to follow instructions using OpenAssistant data, such as Cerebras-GPT, GPT-J, GPT-NeoX.</li>
  <li>Developing integrations for Open Assistant, similar to the plugins proposed for ChatGPT.</li>
  <li>Expanding the Open Assistant data and preparing a corpus for pretraining a large language model (LLM) from scratch.</li>
</ul>

<hr />

<h3 id="contributors">Contributors</h3>

<p>A fantastic team has been working on this project, and you can see an incomplete list of those who contributed to development <a href="https://open-assistant.io/team">here</a>!</p>

<p>If you wish to get in touch with me to discuss the project or otherwise, you can message me on LinkedIn (link below) or email me at <code>oliver ge stanley (_at_) gmail (_dot_) com</code> (address obfuscated to avoid spam).</p>]]></content><author><name>Oliver Stanley</name></author><category term="AI" /><summary type="html"><![CDATA[New open-source language models tuned to follow instructions]]></summary></entry></feed>